Applied AI, built to run in production
Supremacy designs, builds, and operates the whole applied-AI stack — model selection and fine-tuning, retrieval, agents, and the automation that carries the output into the systems your business already runs on.
- Knowledge Base
- AWS
- Atlassian
- Okta
- Intel
- Workflow Automation
- Qantas
- ASML
- Itau Unibanco
- Mayo Clinic
- NCRVoyix
- Breville
One engineering discipline, not six pilots
Most AI programmes stall because every layer belongs to a different team and none of them own the outcome. We build the stack as a single system — models, retrieval, orchestration, and evaluation — so a change anywhere in it is measured against the same bar.
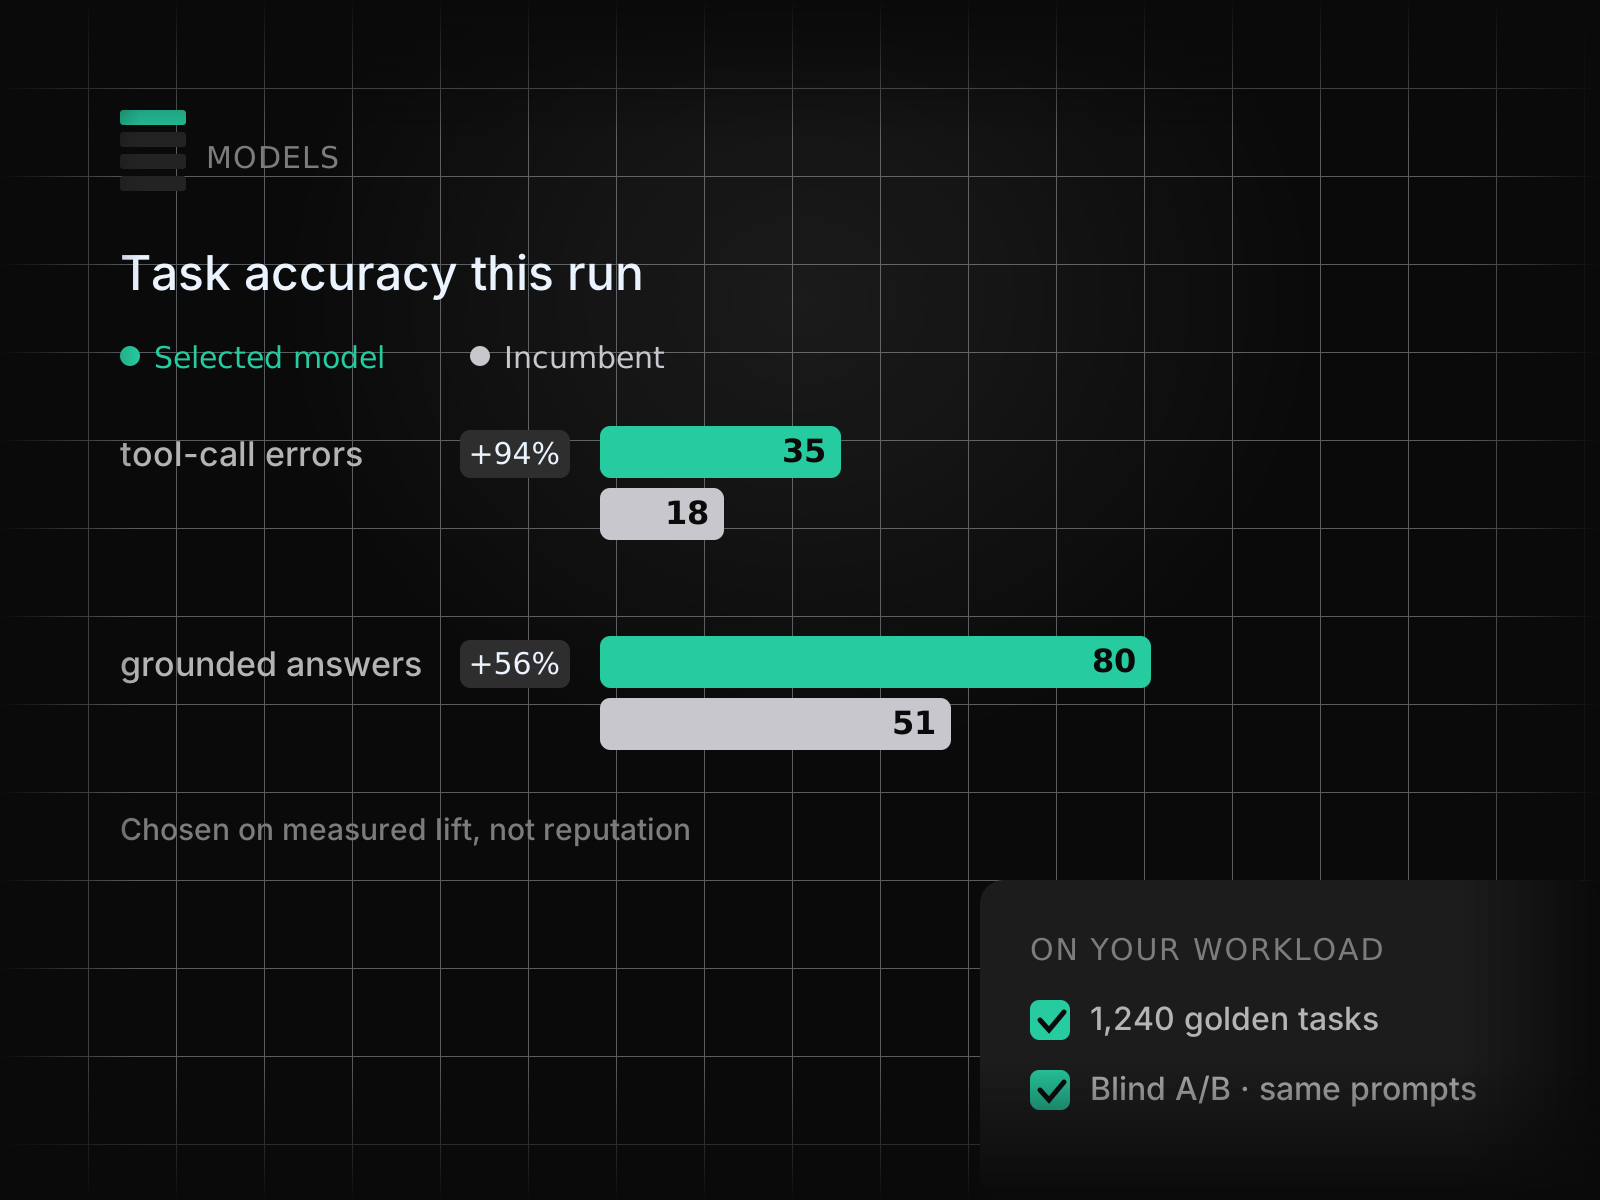
Model selection you can defend
Frontier APIs where reasoning carries the task, open-weight models where cost, latency, or data residency decides it — benchmarked on your workload rather than a public leaderboard.
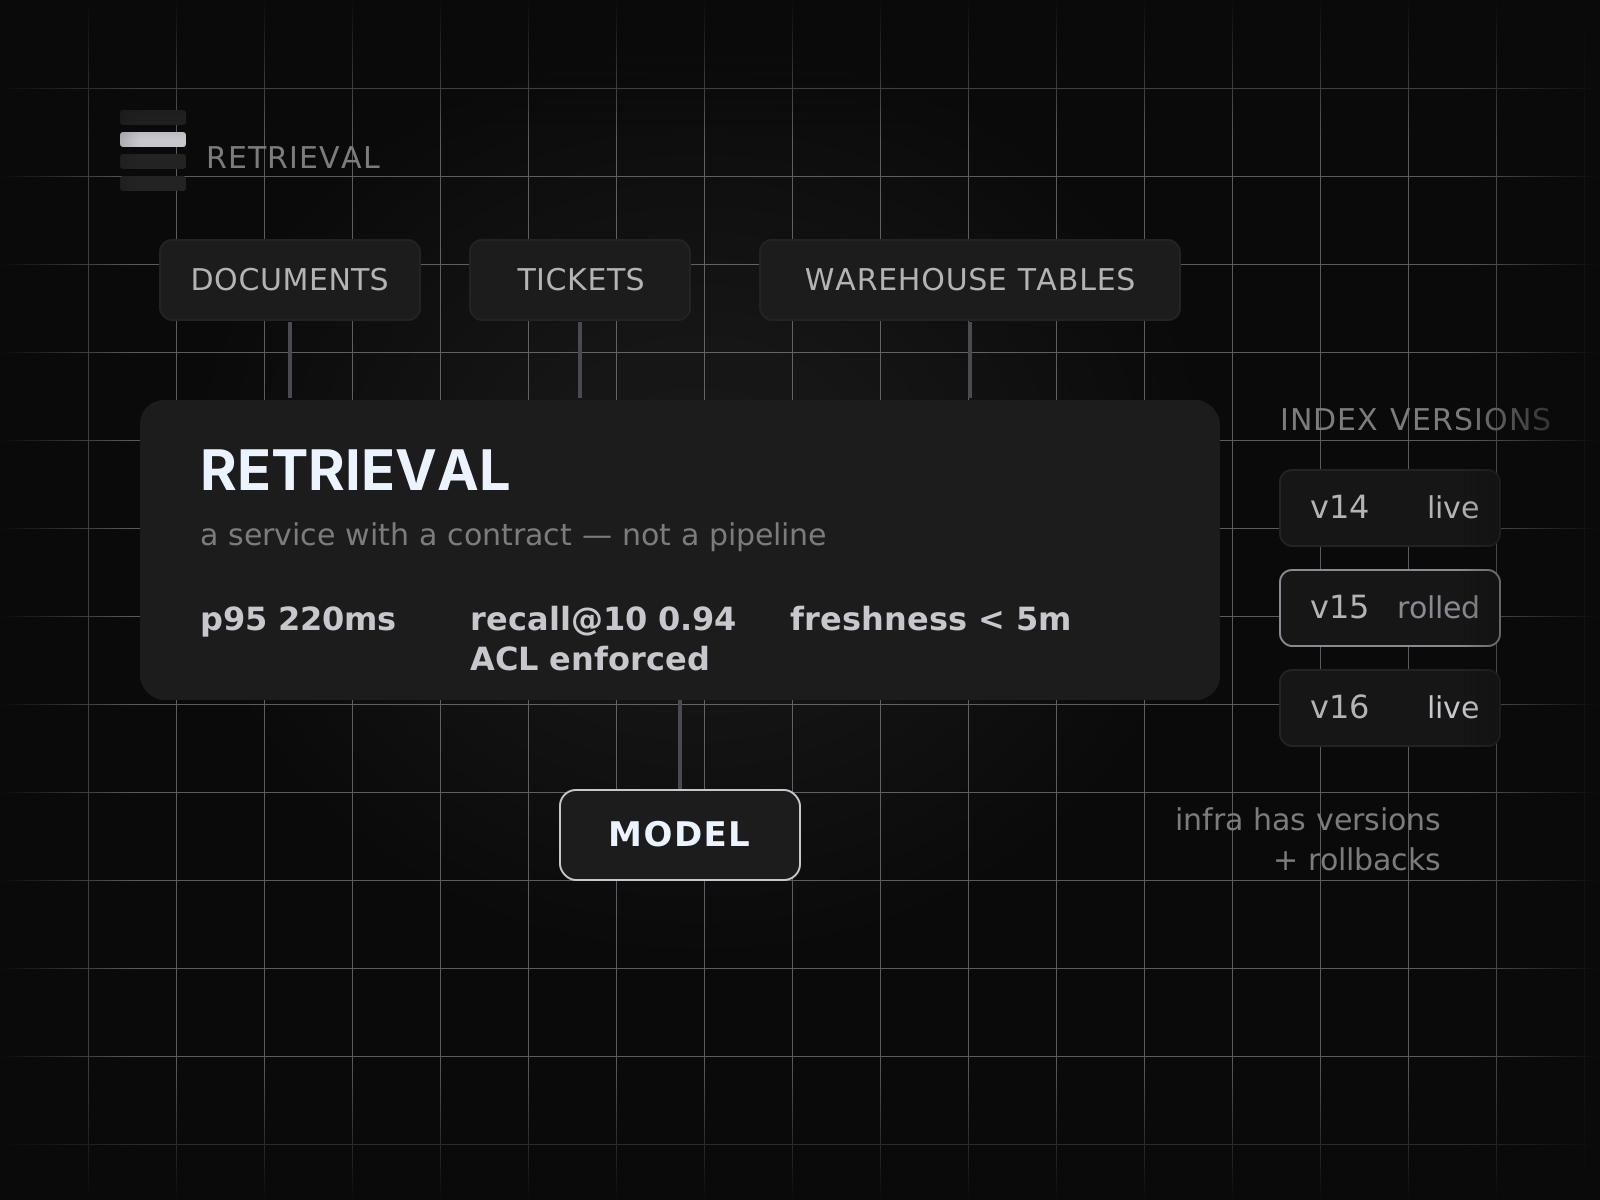
Retrieval treated as infrastructure
Hybrid search, reranking, and grounded citations turn your documents, tickets, and warehouse tables into context the model can actually be held to.
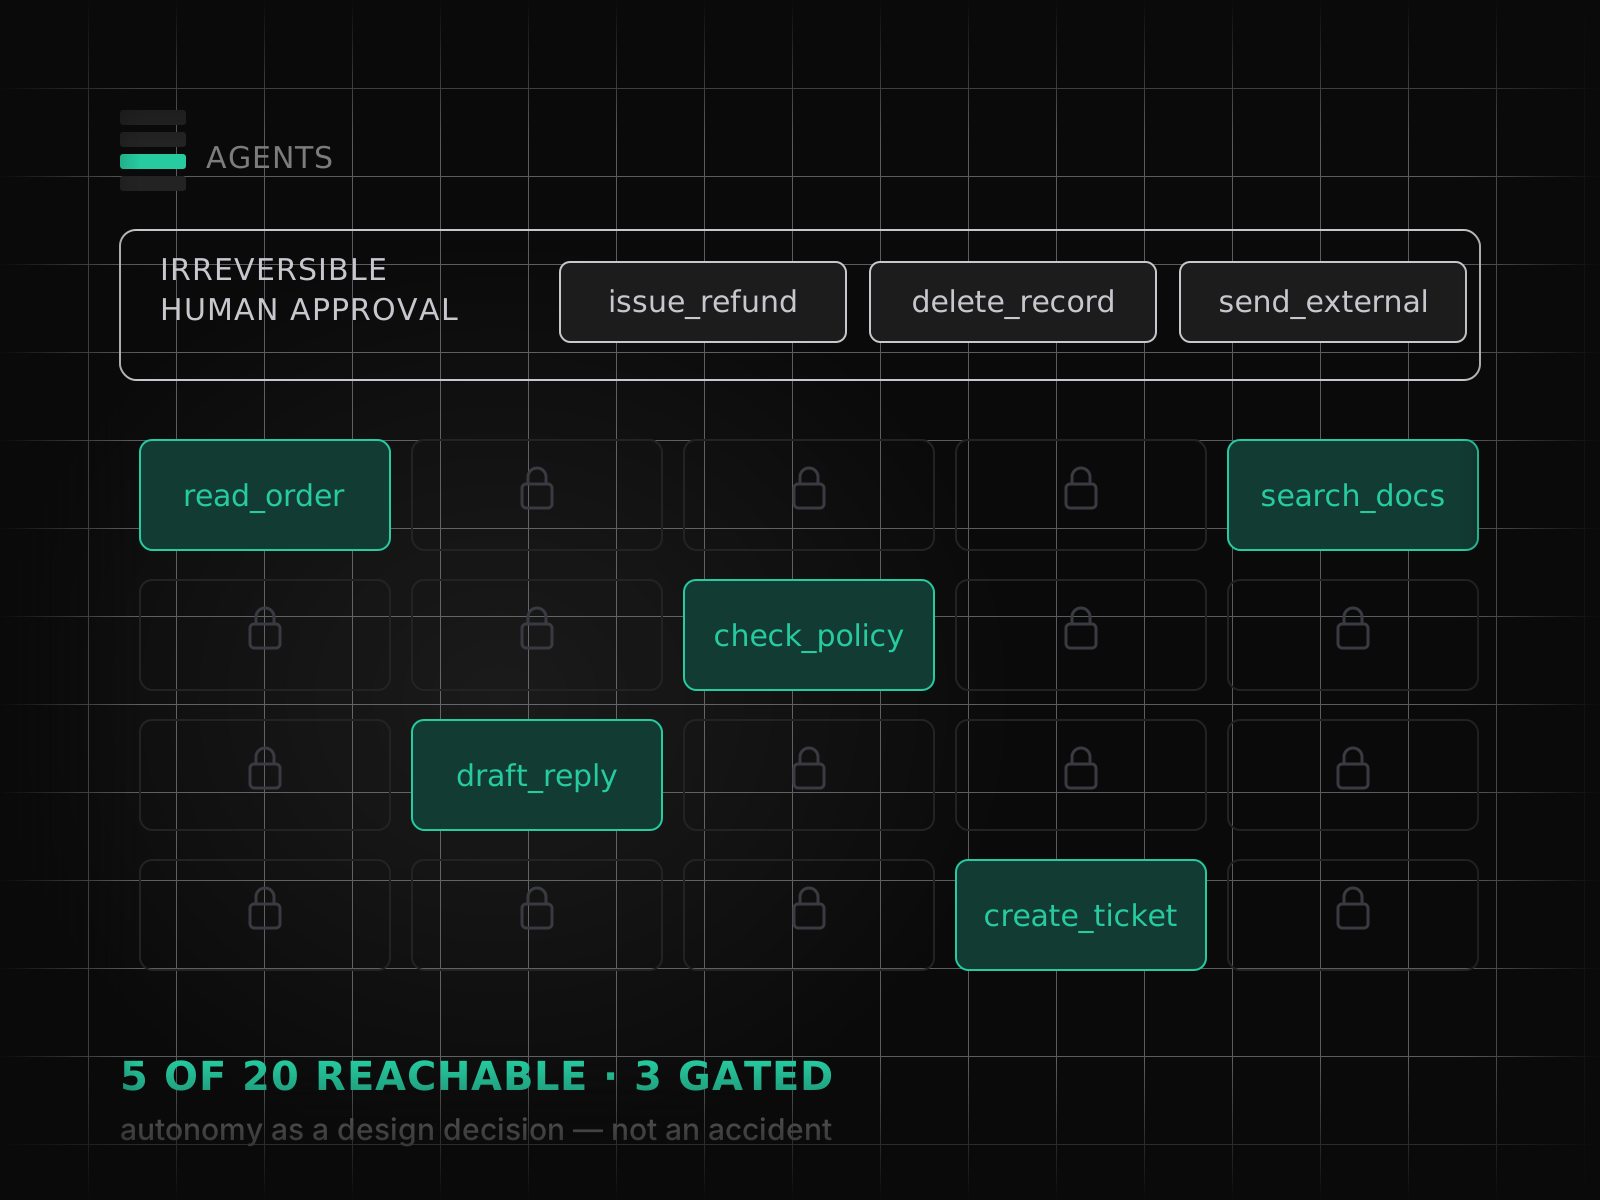
Agents with a bounded blast radius
Tool calls run behind typed schemas, scoped permissions, and human approval on anything irreversible, so autonomy is a design decision instead of an accident.
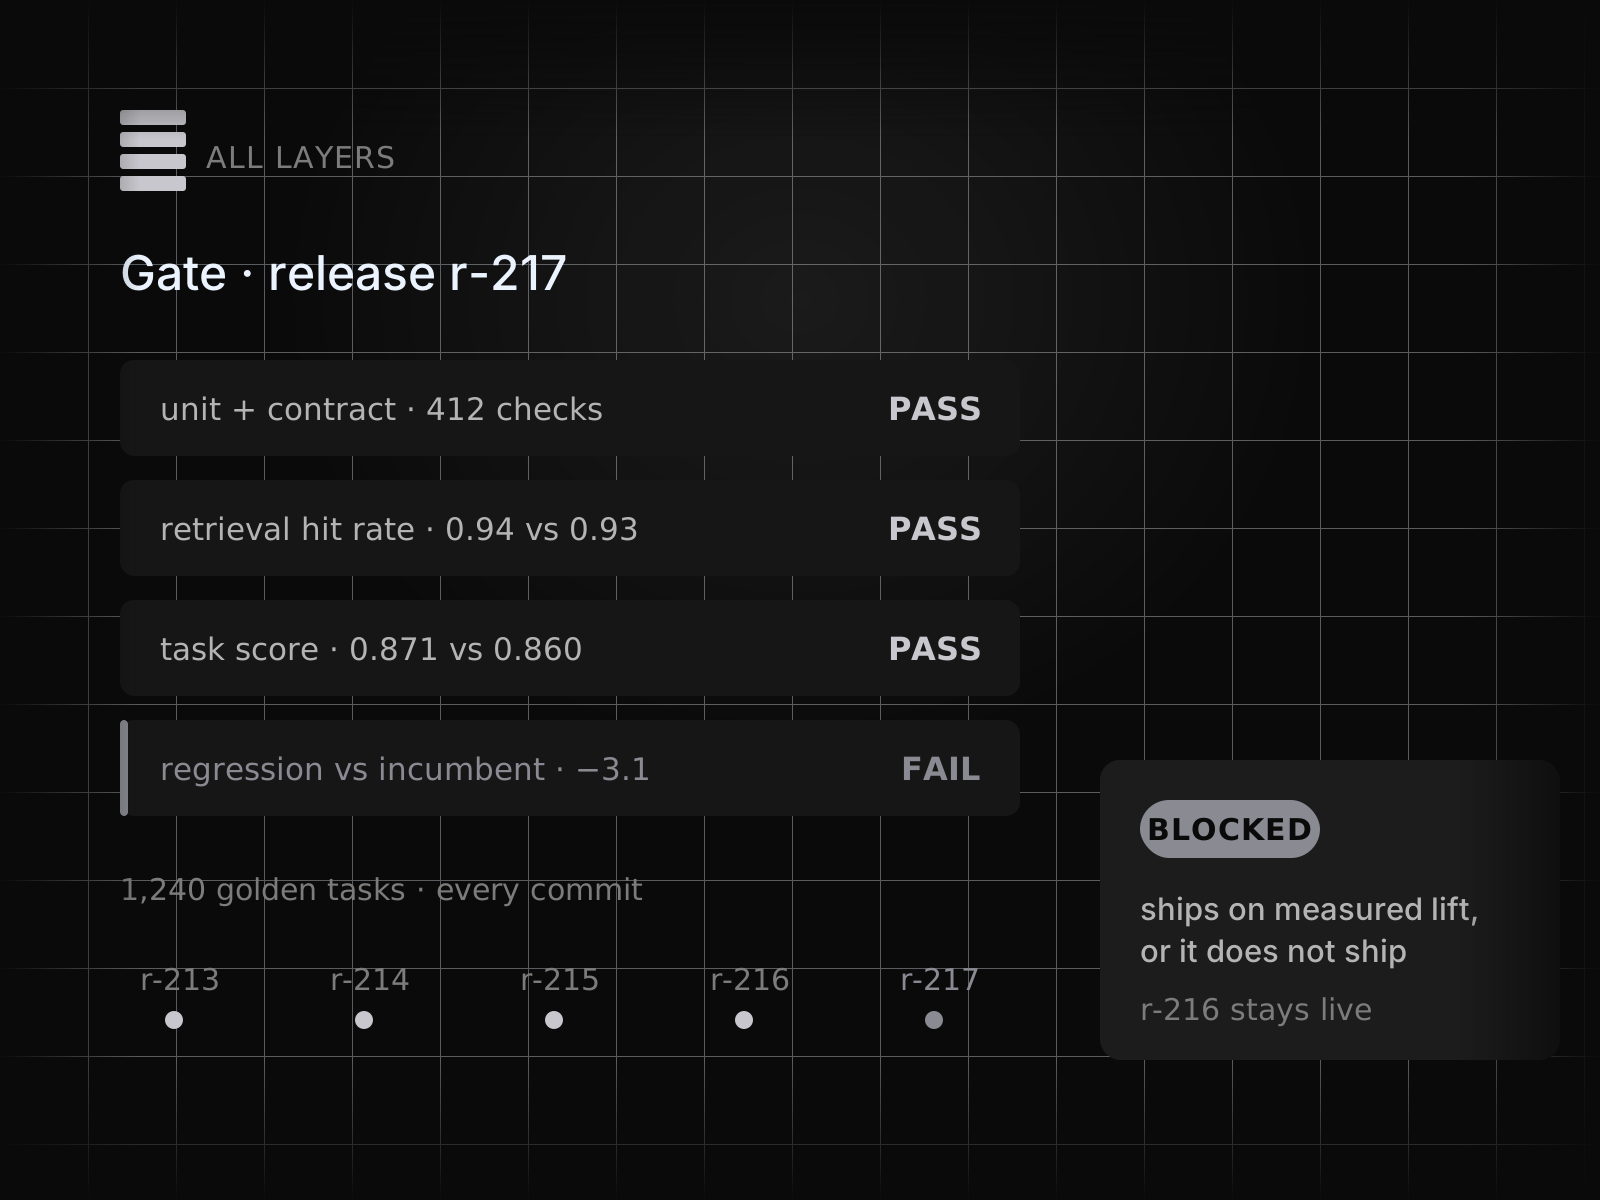
Evaluation from the first commit
Golden sets, regression suites, and LLM-as-judge scoring gate every prompt, model, and index change before a single user sees it.
The part most AI programmes skip
Shipping the model is the easy half. What decides whether the system is still trusted six months later is the operational layer around it — telemetry, cost control, guardrails, and a clear answer to who owns it.
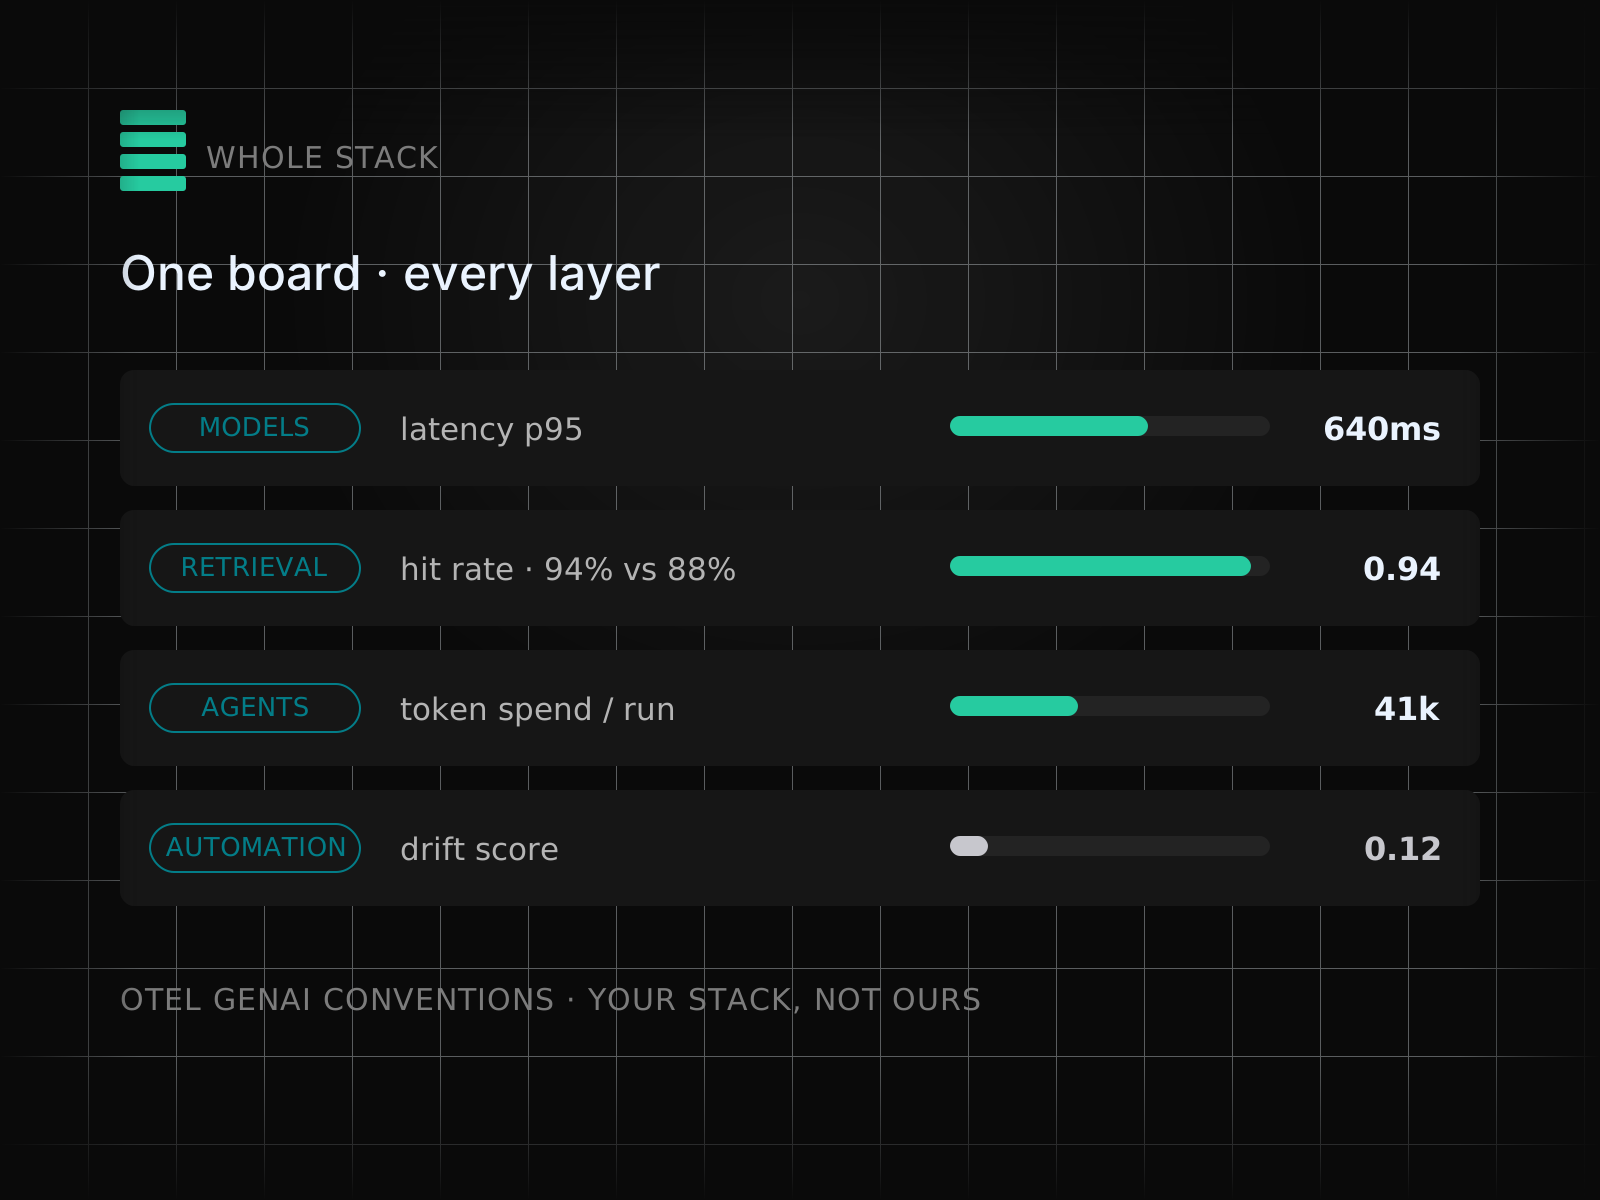
Observability on every call
Latency, token spend, retrieval hit rate, tool-call success, and drift land on one dashboard, so the team accountable for the system can see exactly how it is behaving.
Cost that stays predictable
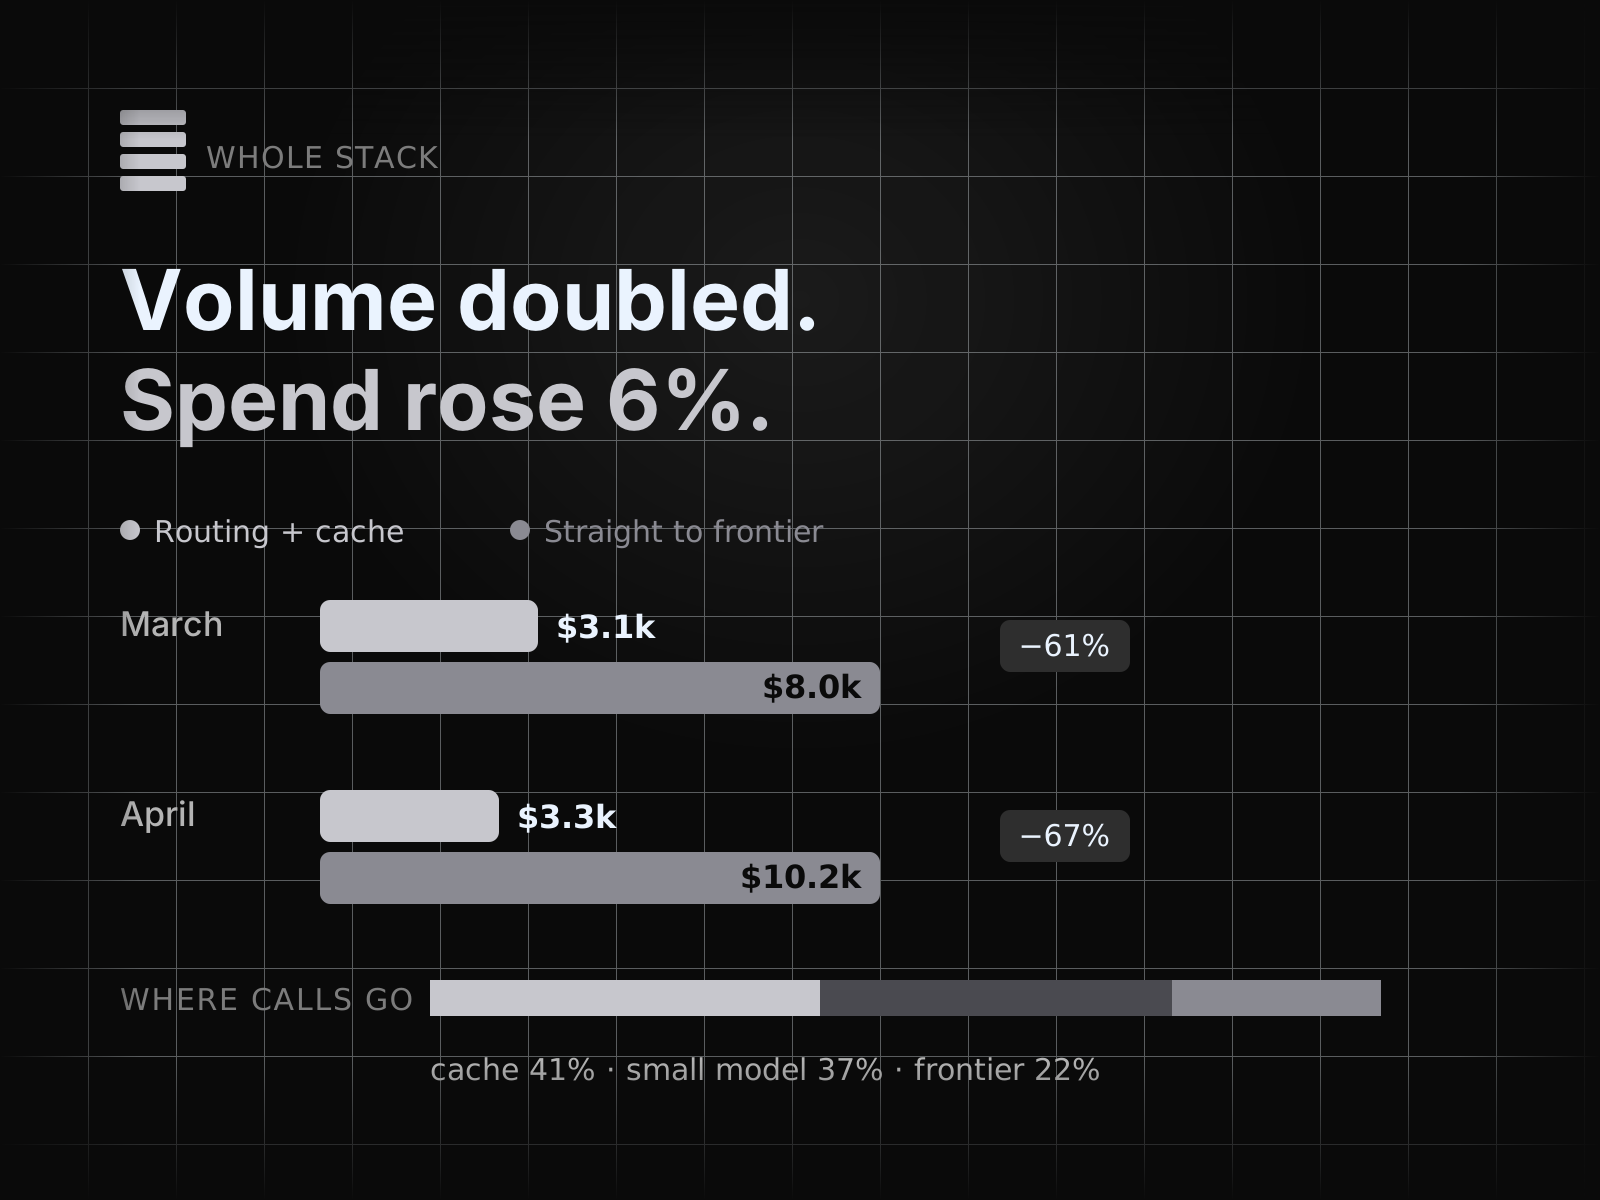
Semantic caching, model routing, and distillation onto smaller models keep unit economics flat as volume grows instead of scaling straight up with it.
Guardrails at the boundary
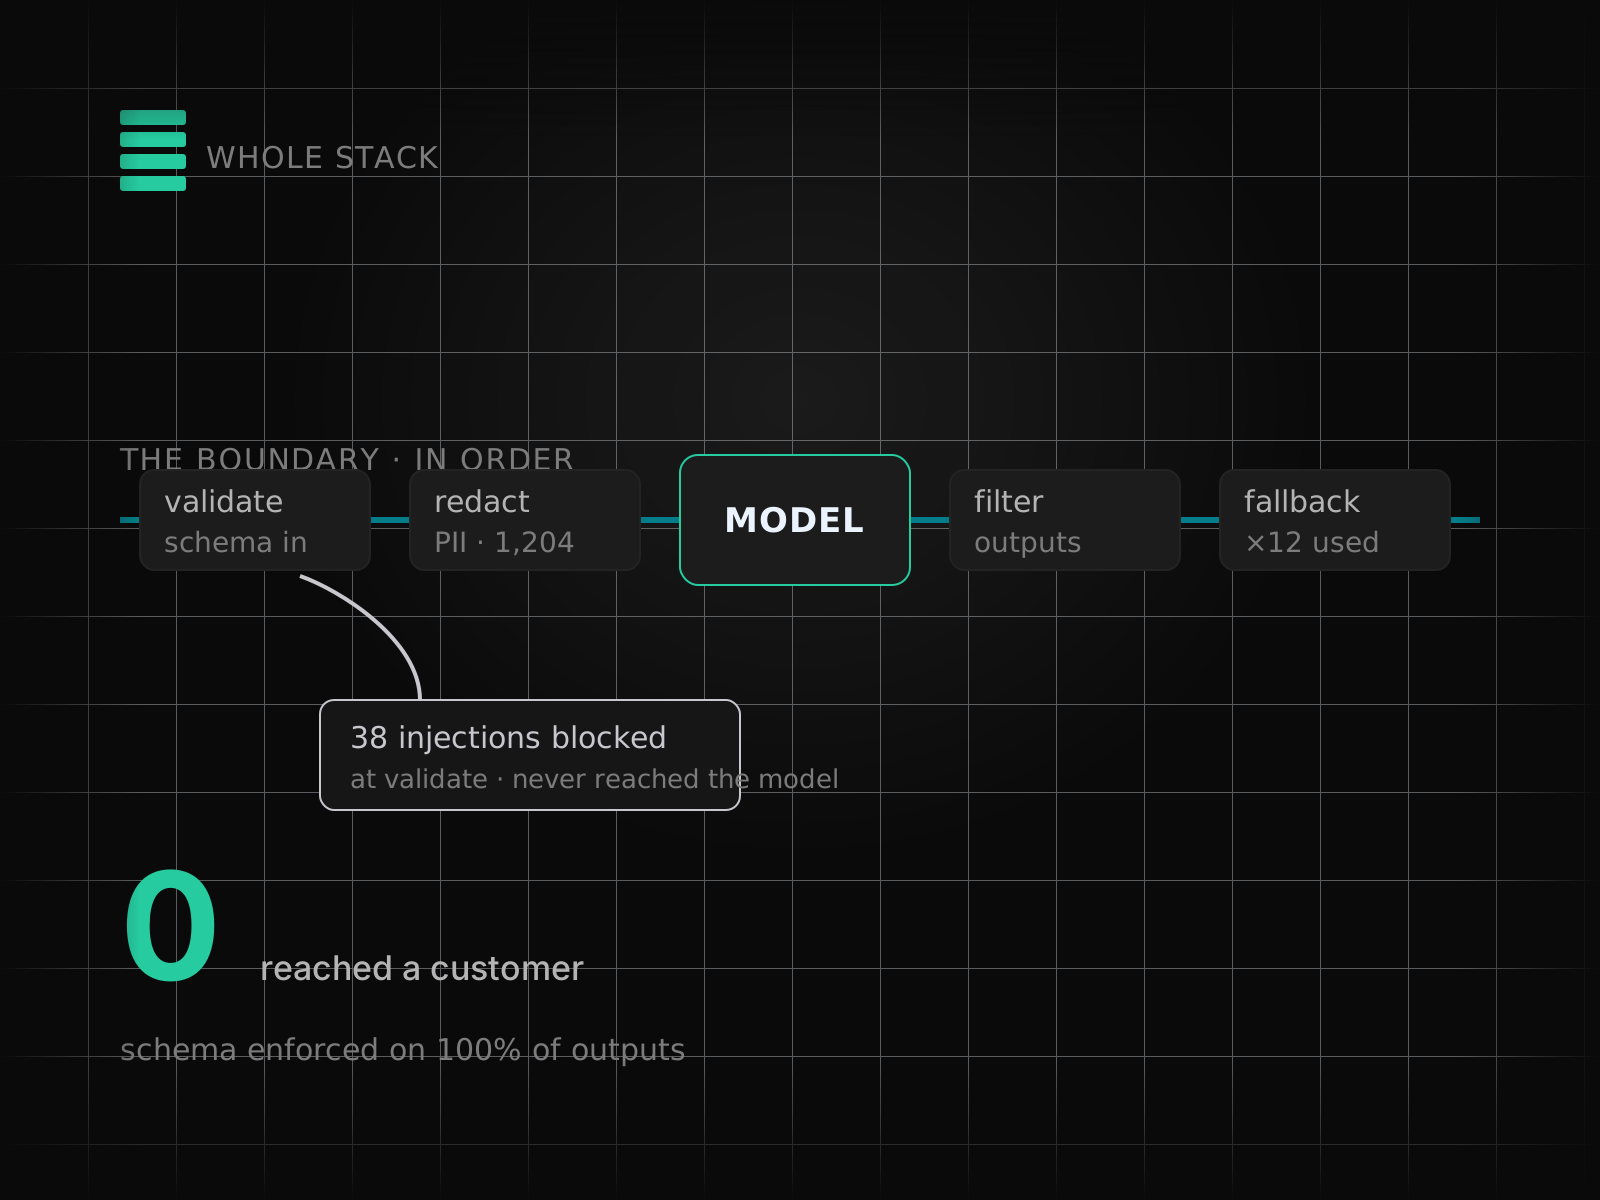
Input validation, PII redaction, output filters, prompt-injection defences, and fallback chains keep failures contained well before they reach a customer.
Ownership you keep
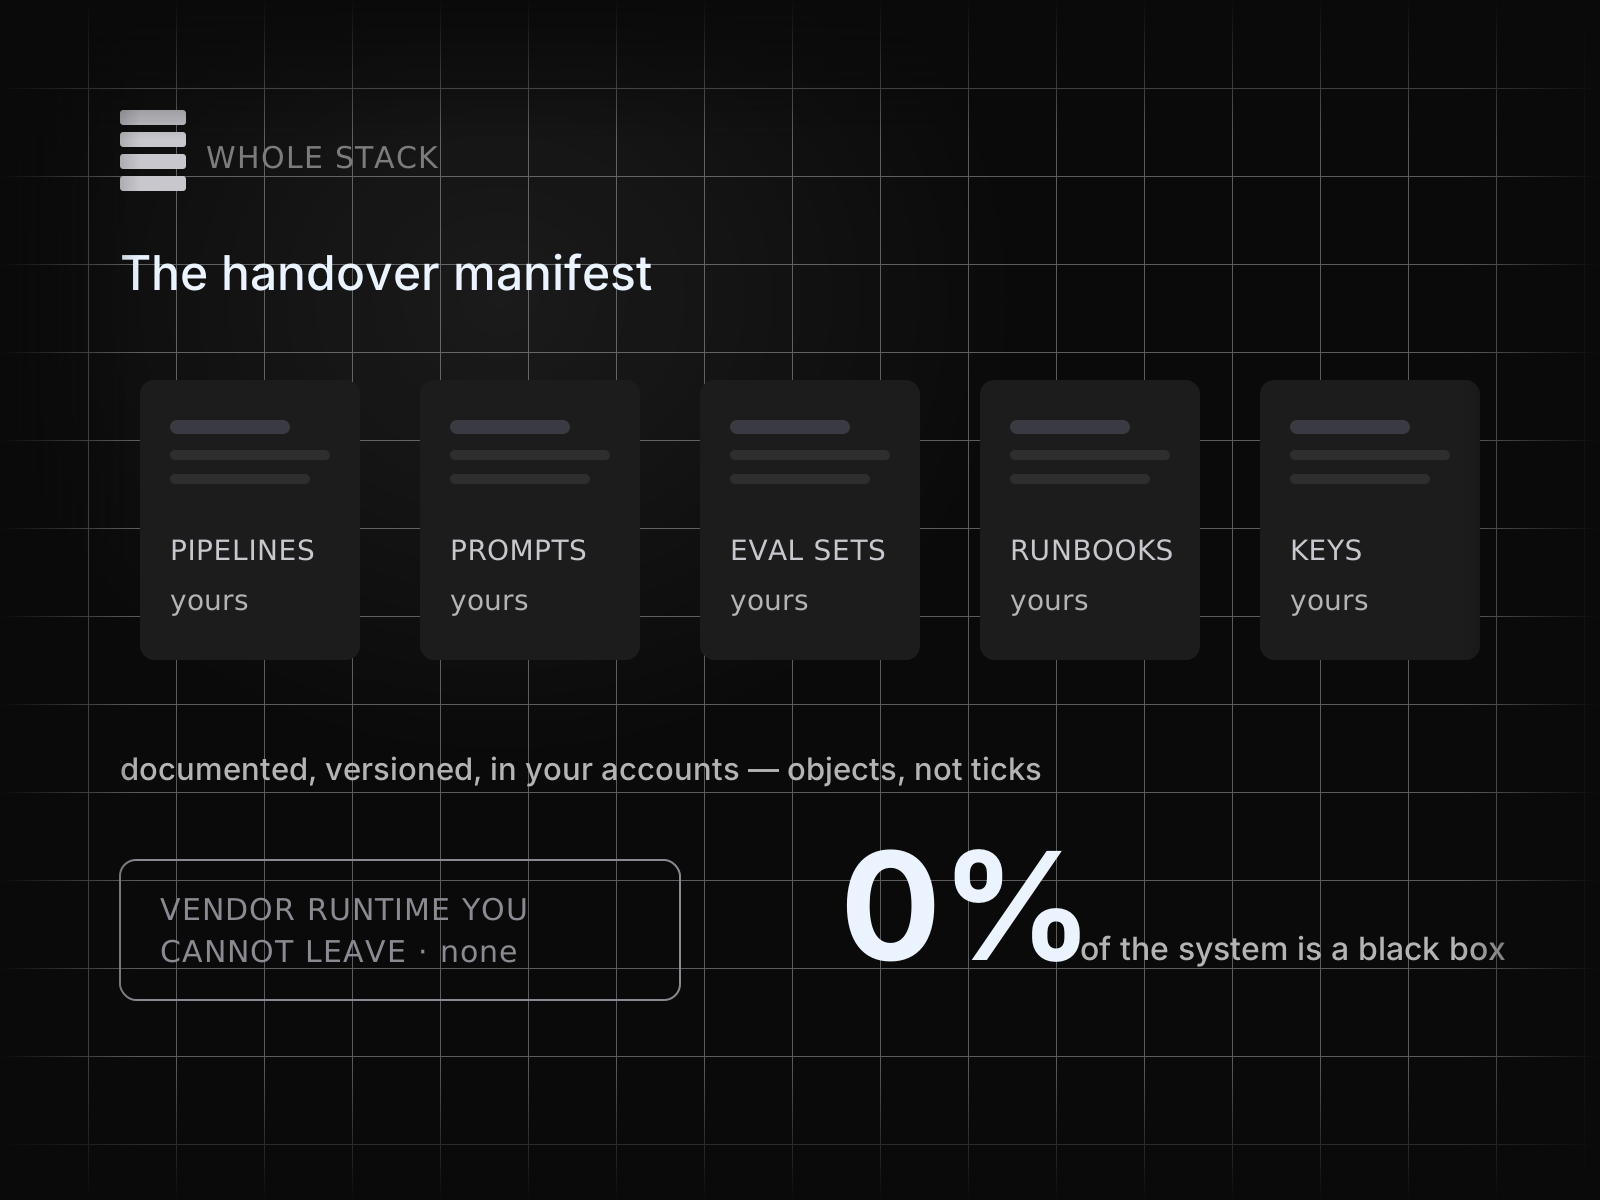
Systems run in your cloud accounts under your keys, with the pipelines, prompts, and evaluation sets documented and handed over. No black box, no runtime you cannot leave.
The questions your risk team will ask
Shipping a system that works is not the same as shipping one your organisation is allowed to run. Compliance evidence, jurisdiction, portability, and agent-specific threats are engineering decisions taken during the build, not paperwork assembled afterwards.
Compliance evidence, not assertions
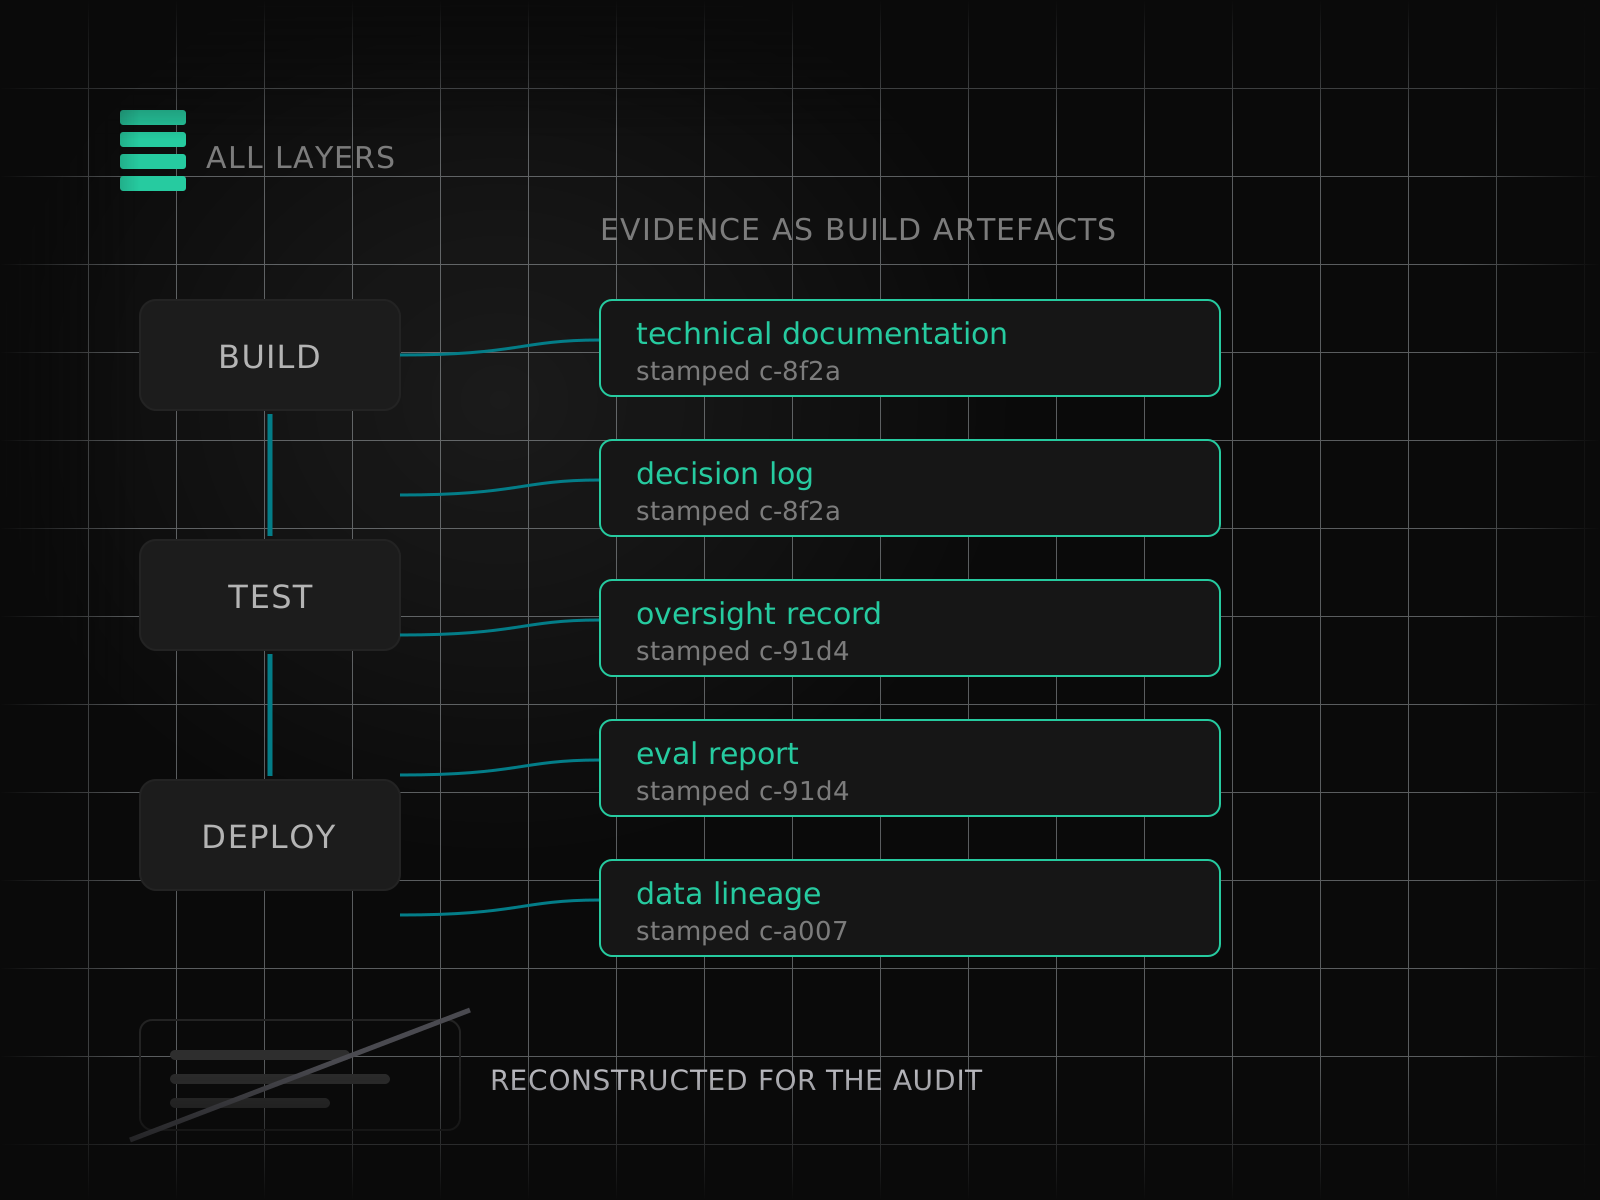
Technical documentation, decision logs, and human-oversight records are produced as build artefacts rather than reconstructed for an audit, so the obligations that apply to your deployment are answered with the system itself.
Sovereignty at inference, not just storage
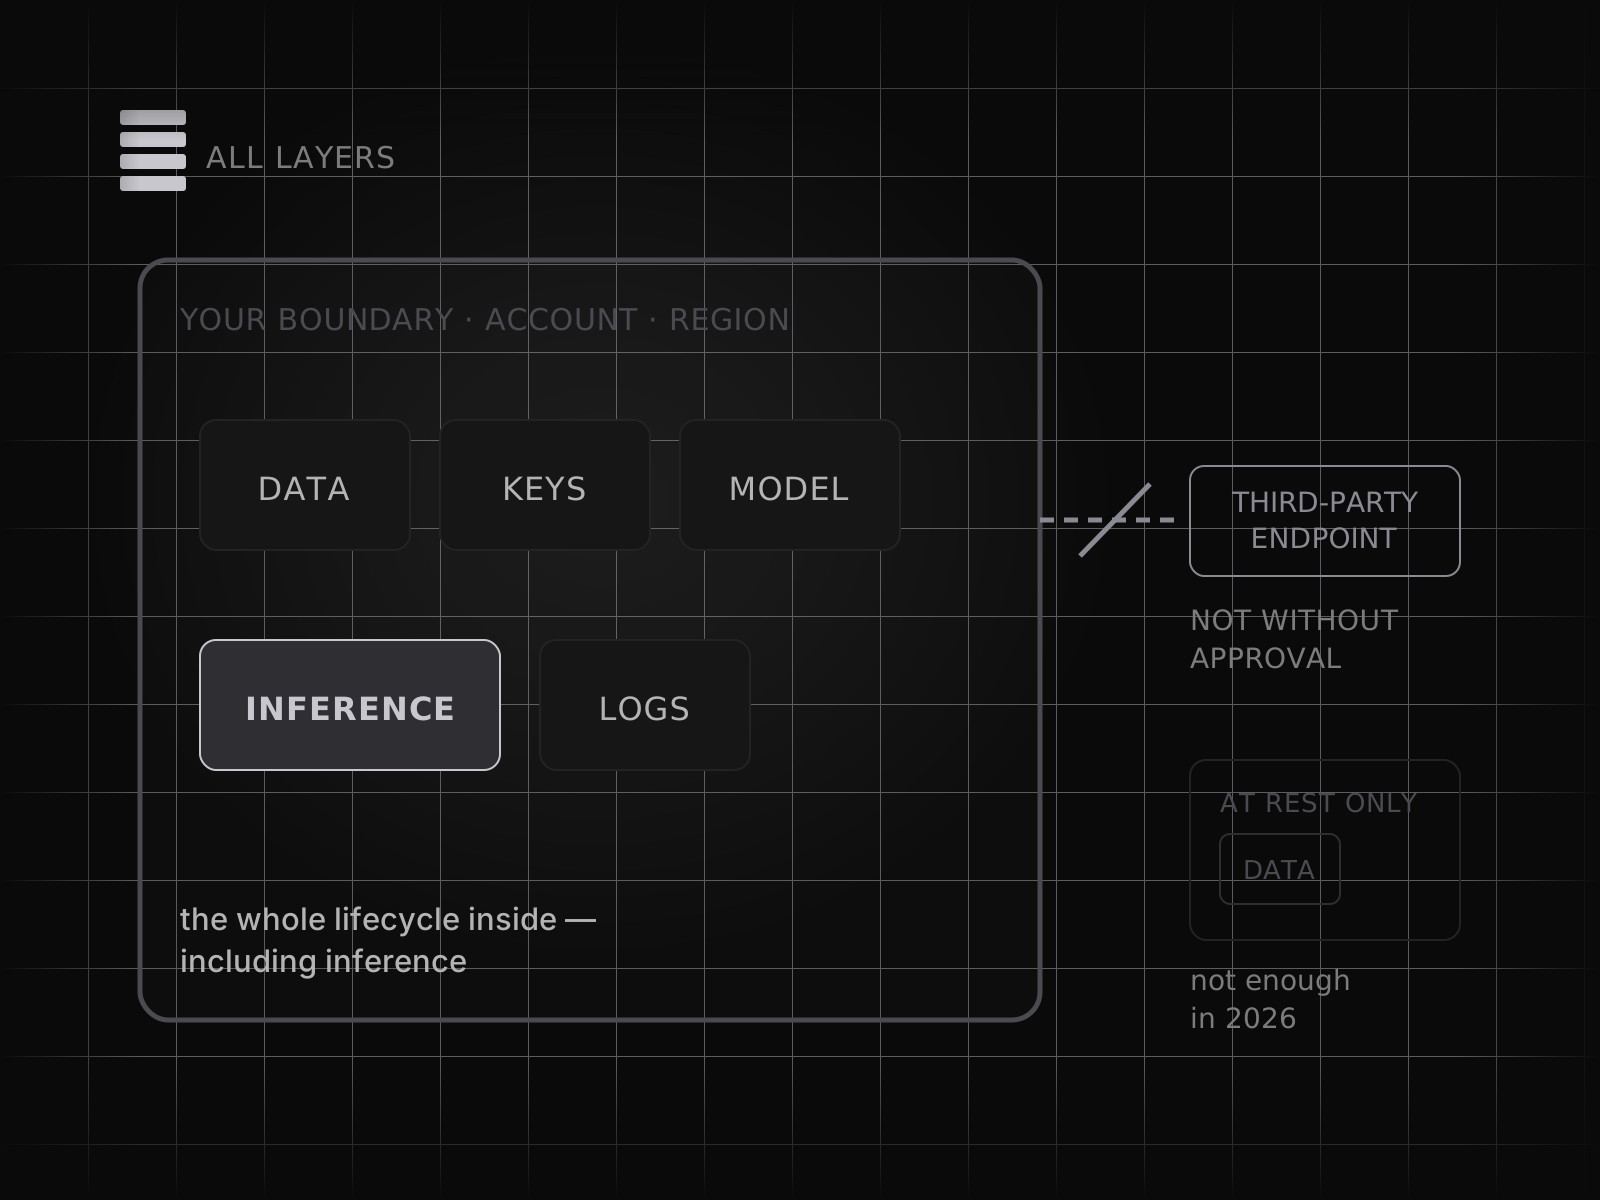
Where a regulator or a contract requires it, the model runs inside your boundary — your account, your region, your keys — at inference time and not only at rest, so residency covers what the system does and not merely where the data sits.
Telemetry you can take with you
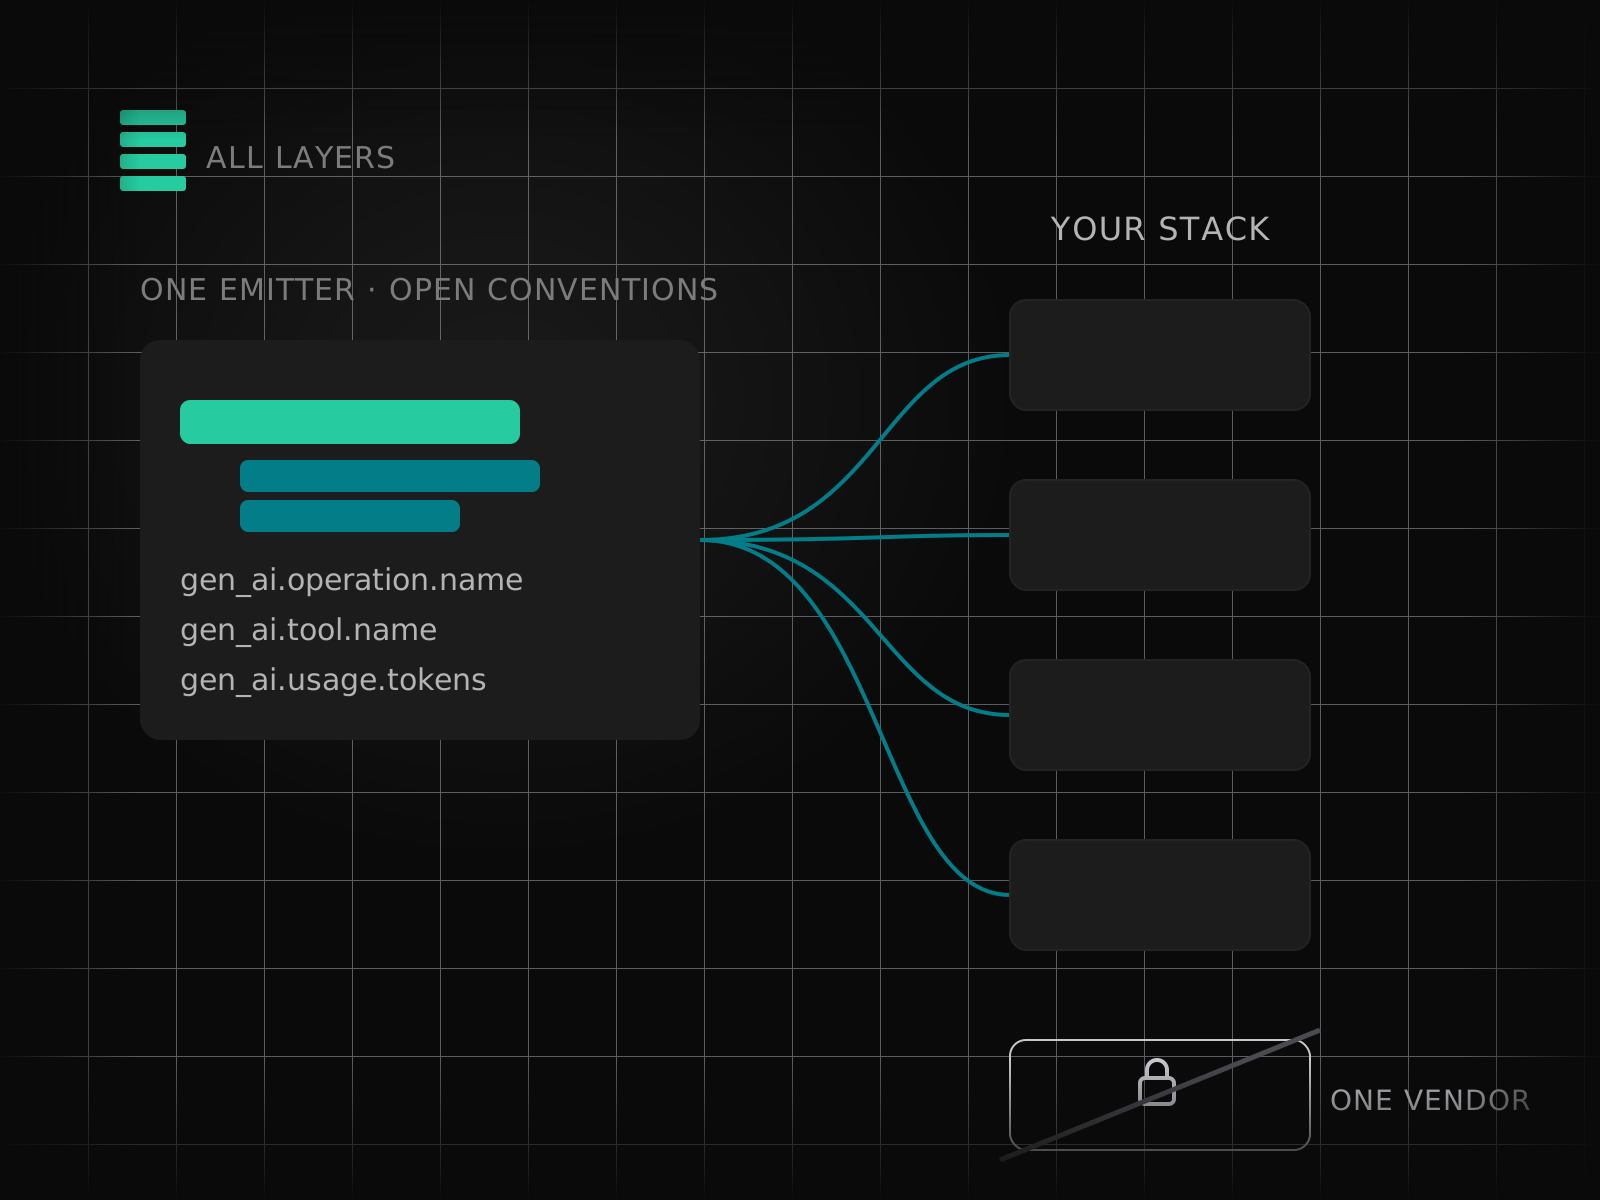
Traces follow the OpenTelemetry conventions for generative AI, so spans, tool calls, and evaluation results land in the observability stack you already run, and monitoring does not depend on us still being here.
Agent threats modelled separately
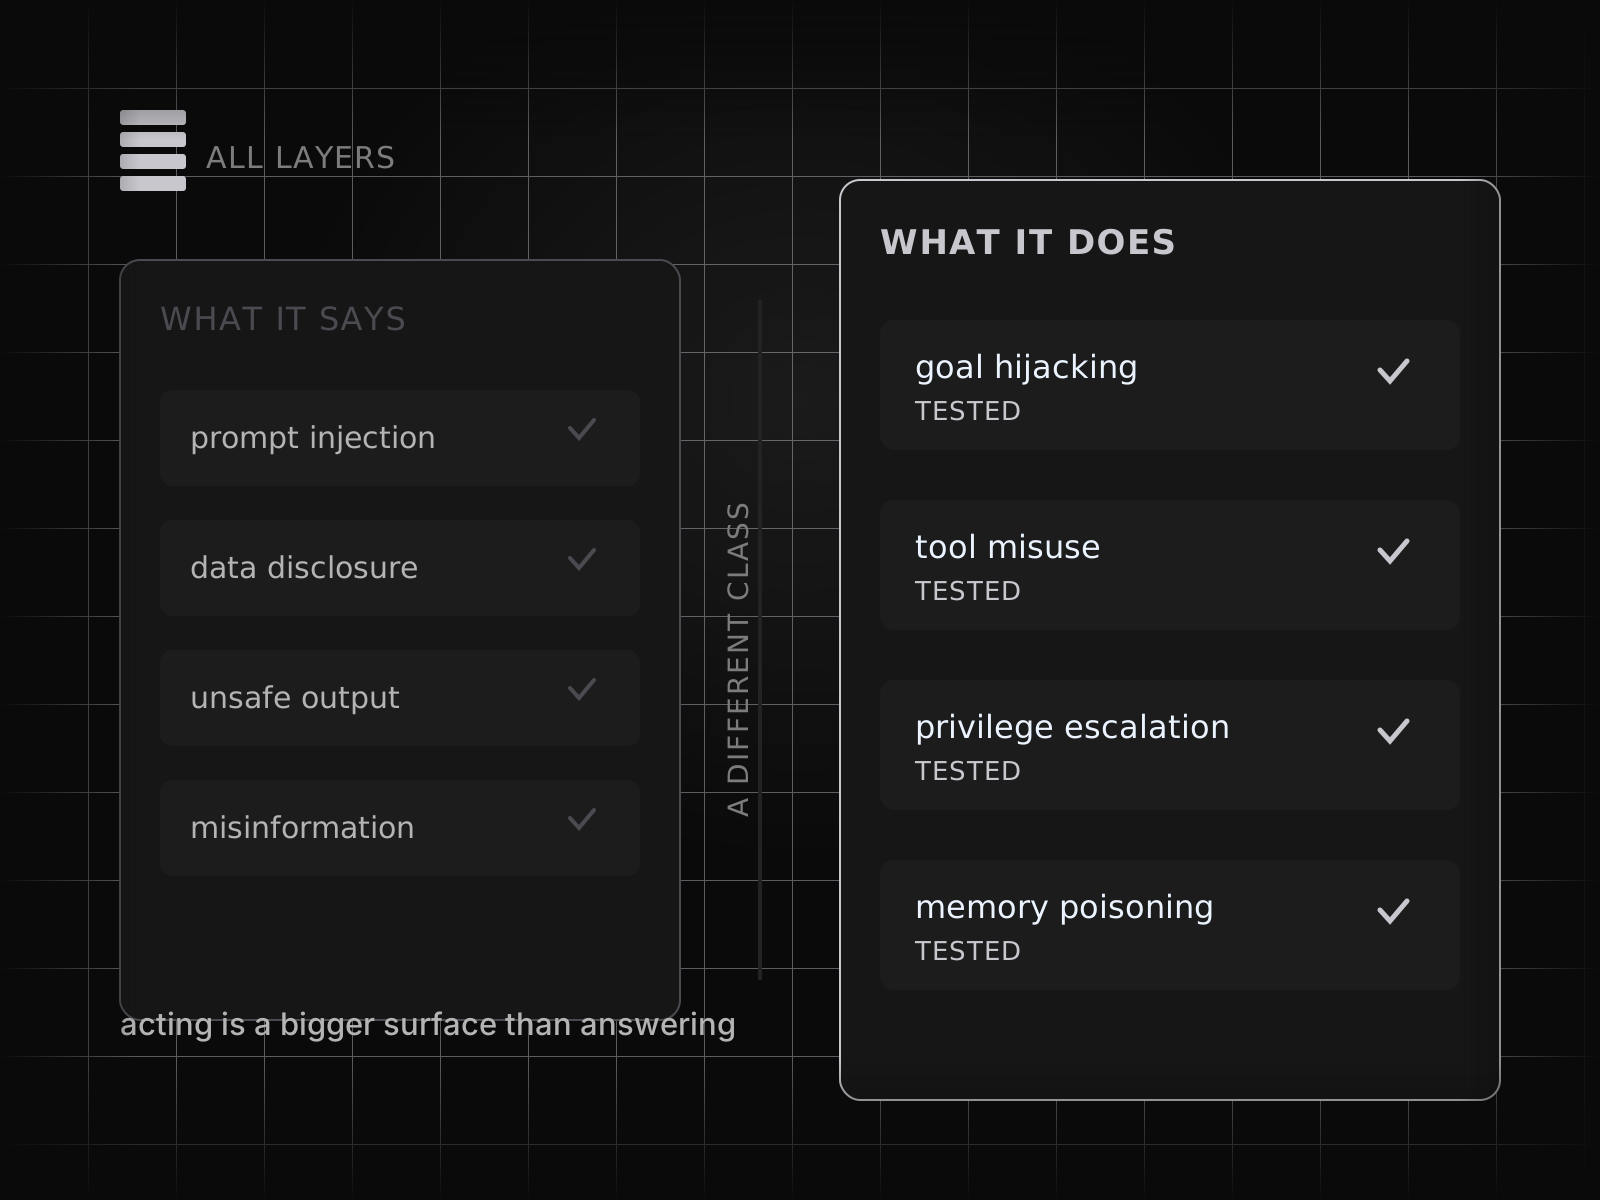
An agent that can act is a different risk surface from a model that can only answer. Goal hijacking, tool misuse, privilege escalation, and memory poisoning are threat-modelled and tested as their own class, alongside the input and output defences at the boundary.
All customer stories
How a logistics operator cut forecast error by a third
Replacing a spreadsheet model with a versioned pipeline and weekly retraining reduced demand-forecast error enough to take a full day of safety stock out of the network.
Read the storyAn analyst assistant that paid back in one quarter
Supremacy grounded an internal assistant in the company’s own warehouse and runbooks, turning hours of SQL and dashboard hunting into a question-and-answer flow the analytics team now relies on daily.
Read the storyCatching model drift before customers did
Live evaluation and alerting flagged a silent accuracy drop in a credit-risk model the week it began, letting the team retrain and redeploy before a single bad decision reached production.
Read the storyFAQs
The full applied stack — data pipelines, model selection and fine-tuning, retrieval, agent orchestration, evaluation, guardrails, and the integrations that put the output inside the workflow where the decision gets made.
Both, chosen per workload. Frontier APIs from Anthropic, OpenAI, and Google where reasoning quality carries the task; open-weight models served on vLLM where cost, latency, or data residency decides it. We benchmark the choice on your data before committing to it.
Your data stays in your environment by default. We work inside your cloud accounts, use customer-managed keys, scope access by role, and route nothing to a third-party provider without explicit approval.
Every build ships with an evaluation harness tied to the metric you are trying to move, plus live tracing on every call, so accuracy, cost, and latency are reported continuously rather than estimated at the end of a quarter.
Usually one workflow with a cost you can already name — a queue somebody is clearing by hand, a document set nobody can search, a decision that waits on an analyst. We instrument it, automate it, and use what that teaches us to scope the next one.